Claude Opus 5.5 vs GPT-6.1 Sol.
Claude Opus 5.5 scores higher, 59 against 55, but GPT-6.1 Sol is almost 8 times cheaper per task.
Anthropic and OpenAI
Data from 13 November 2026.
Which is better?
Claude Opus 5.5 scores higher on Artificial Analysis's Intelligence Index, 59 against 55. It is 3rd of the 58 models it scores, and GPT-6.1 Sol 5th.
On the four coding and reasoning tests, Claude Opus 5.5 wins FrontierCode 2.0, Terminal-Bench 4.0 and HLE Diamond, and GPT-6.1 Sol wins CritPt v2.
Per task, GPT-6.1 Sol is almost 8 times cheaper, $1.27 against $10.04, and they take about the same, 23.3 minutes and 25.2 minutes.
Per token, Anthropic charges $4 per million input tokens and $20 per million output tokens, and OpenAI $2 and $10. They read about the same amount at once, 1 million and 1.05 million tokens.
Choose Claude Opus 5.5 if
- you want the higher score, 59 against 55
- you want it for coding, it wins FrontierCode 2.0 and Terminal-Bench 4.0
- you want it for expert-level questions, it scores 67.9% against 58.8% on HLE Diamond
Choose GPT-6.1 Sol if
- the cost of each task matters, $1.27 against $10.04
At a glance
The score, the cost and the time per task and the tests from Artificial Analysis, read on 13 November 2026 with each model at its highest effort. The price, the context and the release date from Anthropic's and OpenAI's pages. The table of the 58.
Their tests
Keep reading.
- Which AI Model to Use to Build Your Company's Software
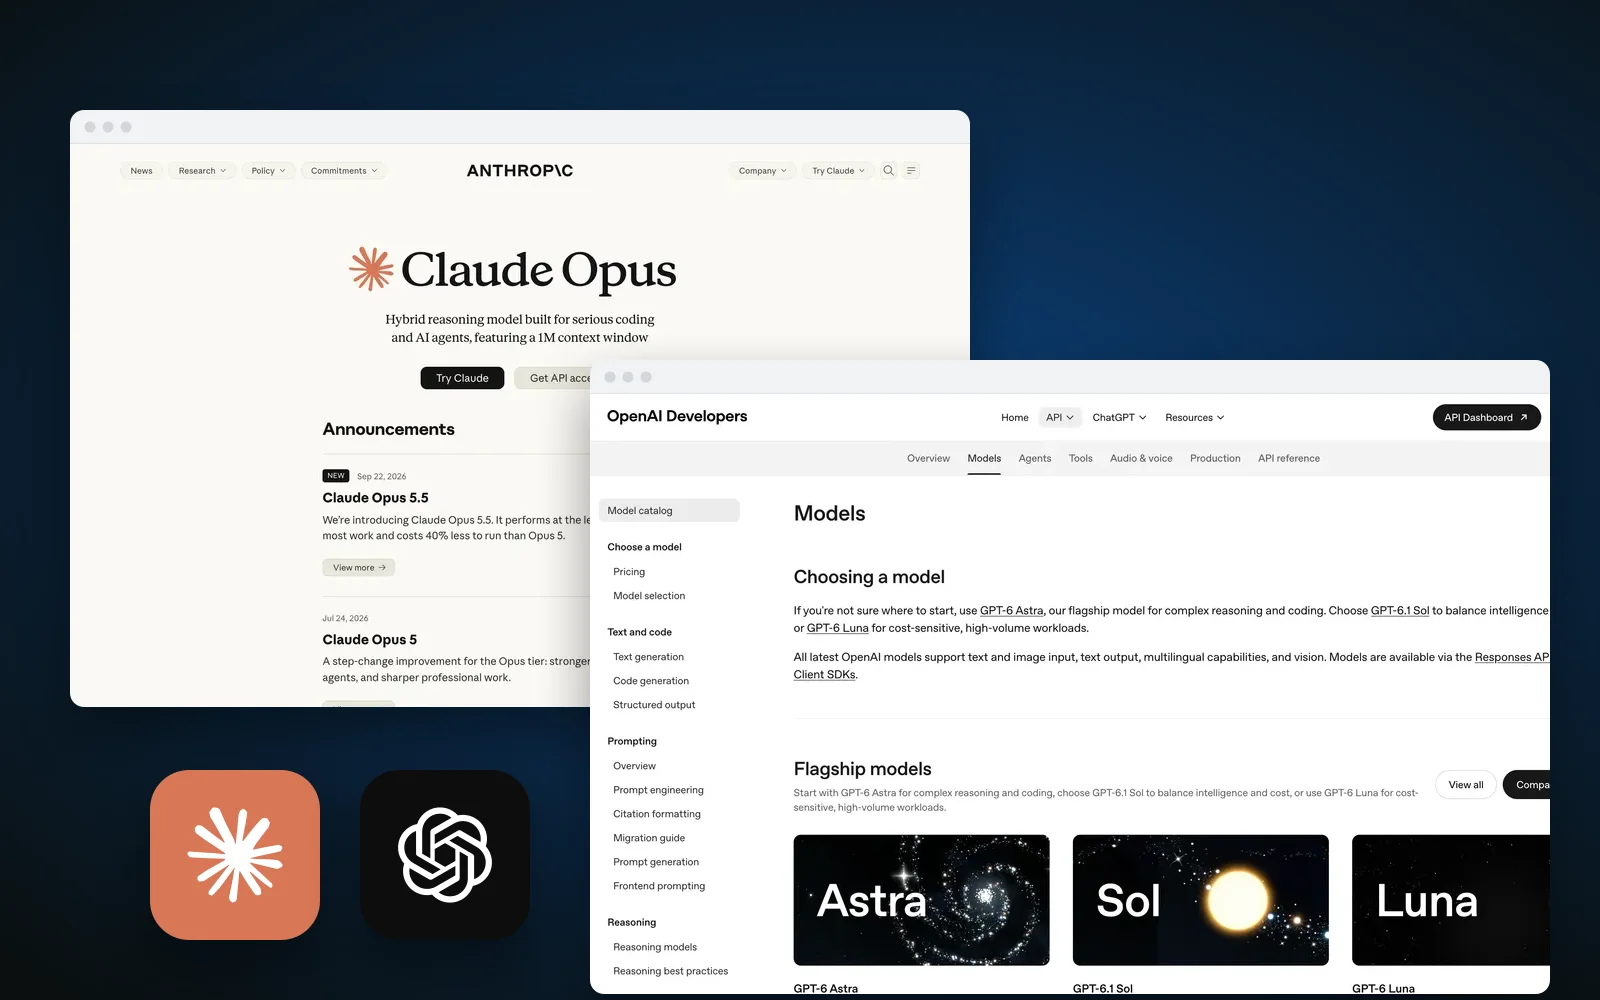 AI · Nov 13, 2026
- Fundaia Case Study, Our Platform to Deploy Apps from GitHub
 Case study · Nov 12, 2026
- Alquilia Case Study, an AI CRM That Qualifies Tenants over WhatsApp
 Case study · Nov 12, 2026
- Natnatura Case Study, a Shopify Supplement Store in Spain and Portugal
 Case study · Nov 11, 2026
- Noura Eclat Case Study, a Shopify Professional Skincare Store in English, Arabic and Spanish
 Case study · Nov 11, 2026
- Claude Code Fixes Failed Deployments, and a Person Decides
 AI · Oct 26, 2026
- Leaderbrock Case Study, an Internal App for a Sales Team's Schedule, Expenses and Routes
 Case study · Nov 10, 2026
- ReservPark Case Study, a Parking App for Street Spots and Hourly Garages
 Case study · Nov 10, 2026
- Almacén-Pro Case Study, a Tool for Stores to Check Incoming Goods by Scanning
 Case study · Nov 11, 2026
- How to Prevent Double Bookings
 Software · Oct 25, 2026
- Boathous Case Study, a Boat Rental Marketplace With a Website, Apps and AI
 Case study · Nov 10, 2026
Questions.
Which one is cheaper?
Per task, GPT-6.1 Sol, with $1.27 against $10.04 on the tasks of Artificial Analysis's index. Per token, GPT-6.1 Sol, with $2 and $10 per million input and output tokens against $4 and $20.
Which one reads more text at once?
They read about the same amount at once, 1 million and 1.05 million tokens.
Can they run on your own servers?
No. Neither has its weights published, so they are used through Anthropic and OpenAI or whoever offers them.
Which one for your company's software?
It depends on the job. We cover it in “Which AI Model to Use to Build Your Company's Software”.